import numpy as np
import scipy
from numpy.linalg import cond, matrix_rank, norm
from scipy.linalg import inv, solve, det, eig, lu
from scipy.linalg import solve_triangularFoundations of Numerical Linear Algebra
Graduate Quantitative Economics and Datascience
Going Beyond “reg y x, robust”
- Data science, econometrics, and macroeconomics are built on linear algebra.
- Numerical linear algebra has all sorts of pitfalls, which become more critical as we scale up to larger problems.
- Speed differences in choosing better algorithms can be orders of magnitude.
- Crucial to know what goes on under-the-hood in Stata/R/python packages for applied work, even if you don’t implement it yourself.
Extra Materials
- Material related to: QuantEcon Python, QuantEcon Data Science, Intro Quantitative Economics with Python
- Self-study and Optional Materials:
Packages
This section uses the following packages:
Basic Computational Complexity
Big-O Notation
For a function \(f(N)\), we say \(f(N)\) is \(O(g(N))\) if there exist positive constants \(C\) and \(N_0\) such that
\[ 0 \leq f(N) \leq C \cdot g(N) \quad \text{for all } N \geq N_0 \]
- Often crucial to know how problems scale asymptotically (as \(N\to\infty\))
- Caution! This is only an asymptotic limit, and can be misleading for small \(N\)
- \(f_1(N) = N^3 + N\) is \(O(N^3)\)
- \(f_2(N) = 1000 N^2 + 3 N\) is \(O(N^2)\)
- For roughly \(N>1000\) use \(f_2\) algorithm, otherwise \(f_1\)
Complexity of Linear Algebra Operations
- \(x \cdot y = \sum_{n=1}^N x_n y_n\) is \(O(N)\) since it requires \(N\) multiplications and additions
- \(A x\) for \(A\in{\mathbb{R}}^{N\times N},x\in{\mathbb{R}}^N\) is \(O(N^2)\) since it requires \(N\) dot products, each \(O(N)\)
- \(A B\) for \(A,B\in{\mathbb{R}}^{N\times N}\) is \(O(N^3)\) since it requires \(N^2\) dot products, each \(O(N)\)
- Solving \(A x = b\) for general \(A\in{\mathbb{R}}^{N\times N}\) is \(O(N^3)\), the same order as a matrix product
- Complexity can measure time, primitive operations (addition, multiplication), or storage. Here we count operations.
Example: Solving Least Squares with an Optimizer
Let \(A\in{\mathbb{R}}^{M\times N}\) have full column rank, with \(b\in{\mathbb{R}}^M\) and \(M\gg N\).
\[ \min_{x\in{\mathbb{R}}^N} \lVert Ax-b\rVert_2^2, \qquad G=A^{\top}A,\quad c=A^{\top}b. \]
Suppose a simple optimizer takes \(K\) iterations, each evaluating \(Gx-c\).
| Algorithm | Total computational cost | Extra storage |
|---|---|---|
| Recompute from rows of \(A,b\) each iteration | \(O(KMN)\) | \(O(N)\) |
| Precompute and store \(G,c\) | \(O(\max(M,K)N^2)\) | \(O(N^2)\) |
| Direct QR solve (factor a copy of \(A\)) | \(O(MN^2)\) | \(O(MN)\) |
| Normal equations + Cholesky | \(O(MN^2)\) | \(O(N^2)\) |
Extra storage excludes the retained inputs \(A,b\).
Numerical Precision
Machine Epsilon
For a given datatype, \({\epsilon_{\mathrm{mach}}}= \min_{\delta > 0} \left\{ \delta : 1 + \delta > 1 \right\}\)
- Computers have finite precision. 64-bit typical, but 32-bit on GPUs
machine epsilon for float64 = 2.220446049250313e-16
1 + eps/2 == 1? True
machine epsilon for float32 = 1.1920928955078125e-07
Basic Linear Algebra
Norms
Euclidean Norm
For \(x \in {\mathbb{R}}^N\), the Euclidean (or \(L^2\)) norm is
\[ ||x||_2 = \sqrt{\sum_{n=1}^N x_n^2} \]
- Complexity is \(O(N)\), square \(N\) times then \(N\) additions
x = np.array([1, 2, 3]) # Calculating different ways (in order of preference)
print(np.sqrt(sum(xval**2 for xval in x))) # manual with comprehensions
print(np.sqrt(np.sum(np.square(x)))) # broadcasts
print(norm(x)) # built-in to numpy norm(x, ord=2) alternatively
print(f"||x||_2^2 = {norm(x)**2} = {x.T @ x} = {np.dot(x, x)}")
3.7416573867739413
3.7416573867739413
3.7416573867739413
||x||_2^2 = 14.0 = 14 = 14Solving Systems of Equations
- Solving \(A x = b\) for \(x\) is equivalent \(A^{-1} A x = A^{-1} b\)
- Then since \(A^{-1}A = I\), and \(I x = x\), we have \(x = A^{-1} b\)
- Careful since matrix algebra is not commutative!
Using the Inverse Directly
- Can replace the
solvewith a calculation of an inverse - But it can be slower or less accurate than solving the system directly
Linear Combinations
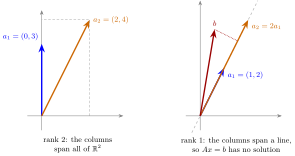
We can think of solving a system as finding the linear combination of columns of \(A\) that equal \(b\)
Column Space and Rank
- The column space of a matrix represents all possible linear combinations of its columns.
- It is the set of \(b\) for which \(A x = b\) has a solution
- The rank of a matrix is the dimension of its column space
Hence, can solve \(A x = b\) for any \(b \in {\mathbb{R}}^2\) since the column space is the entire space \({\mathbb{R}}^2\)
Singular Matrices
On the other hand, note
So we can only solve \(A x = b\) for \(b \propto \begin{bmatrix} 1 \\ 2 \end{bmatrix} \propto \begin{bmatrix} 2 \\ 4 \end{bmatrix}\)
Checking Singularity
A = np.array([[1, 2],
              [2, 4]])
# An (expensive) way to check if A is singular is if det(A) = 0
print(det(A) == 0.0)
print(matrix_rank(A) != A.shape[0]) # or check rank
# Check before inverting or use exceptions
try:
    inv(A)
    print("Matrix is not singular (invertible).")
except np.linalg.LinAlgError:
    print("Matrix is singular (non-invertible).")
True
True
Matrix is singular (non-invertible).Determinant is Not Scale Invariant
- Reminder: numerical precision in calculations makes it hard to compare to zero
- The determinant is useful but depends on the scale of the matrix
- A scale-free alternative is the condition number \(\kappa(A)\), defined with eigenvalues later in this deck
det(A)=-1e-08, det(K*A)=-100
cond(A)=1e+09, cond(K*A)=1e+09,
det(inv(A))=-1e+08, cond(inv(A))=1e+09
Solving Linear Systems of Equations
Solving Systems with Multiple RHS
- Inverse is nice because you can reuse the \(A^{-1}\) to solve \(A x = b\) for many \(b\)
- However, you can do this with
solveas well - Or can reuse LU factorizations (discussed next)
[[-1.         -1.33333333]
 [ 1.          1.5       ]]
Checking: A*[-1.  1.] = [2. 1.] = [2 1], column of B
LU(P) Decompositions
- For any square \(A\), SciPy uses \(A = P L U\): \(P\) is a permutation matrix, \(L\) lower triangular with diagonal ones, and \(U\) upper triangular.
- \(P^{-1} = P^{\top}\), so \(P^{\top} A = L U\).
- Other texts use \(P A = L U\) with SciPy’s \(P^{\top}\) as their \(P\); check the math and docs.
P, L, and U
- \(L\) is invertible; if \(A\) is singular, \(U\) is singular.
LU for Non-Singular Matrices
Pivoting is Needed in General
- Gaussian elimination can fail without reordering rows: here, \(\mathrm{row}_2 + c\,\mathrm{row}_1\) has first entry \(1\) for every \(c\).
- Invertible: \(A = \begin{bmatrix}0 & 1 \\ 1 & 0\end{bmatrix}\)
- \(A = \underbrace{\begin{bmatrix}0 & 1 \\ 1 & 0\end{bmatrix}}_{P}\underbrace{\begin{bmatrix}1 & 0 \\ 0 & 1\end{bmatrix}}_{L}\underbrace{\begin{bmatrix}1 & 0 \\ 0 & 1\end{bmatrix}}_{U}\)
- Singular: \(A = \begin{bmatrix}0 & 0 \\ 1 & 0\end{bmatrix}\)
- \(A = \underbrace{\begin{bmatrix}0 & 1 \\ 1 & 0\end{bmatrix}}_{P}\underbrace{\begin{bmatrix}1 & 0 \\ 0 & 1\end{bmatrix}}_{L}\underbrace{\begin{bmatrix}1 & 0 \\ 0 & 0\end{bmatrix}}_{U}\)
Pivoting and Numerical Stability
- \(A = \begin{bmatrix}\varepsilon & 1 \\ 1 & 0.1\end{bmatrix}\) to solve \(A x = b \equiv \begin{bmatrix}1 & 1\end{bmatrix}^{\top}\) with \(\varepsilon = 2{\epsilon_{\mathrm{mach}}}\approx 4.44\times10^{-16}\) in float64
- Without pivoting
- Eliminate the first entry: \(\begin{bmatrix}1 & 0.1\end{bmatrix} - \frac{1}{\varepsilon}\begin{bmatrix}\varepsilon & 1\end{bmatrix} = \begin{bmatrix}0 & 0.1-1/\varepsilon\end{bmatrix} \approx \begin{bmatrix}0 & -1/\varepsilon\end{bmatrix}\)
- \(\underbrace{\begin{bmatrix}1 & 0 \\ 1/\varepsilon & 1\end{bmatrix}}_{L}\underbrace{\begin{bmatrix}\varepsilon & 1 \\ 0 & -1/\varepsilon\end{bmatrix}}_{U} \approx \begin{bmatrix}\varepsilon & 1 \\ 1 & 0\end{bmatrix} \ne A\), with \(x \approx \begin{bmatrix}1 & 1\end{bmatrix}^{\top}\)
- With pivoting: swap the rows
- Eliminate the first entry: \(\begin{bmatrix}\varepsilon & 1\end{bmatrix} - \varepsilon\begin{bmatrix}1 & 0.1\end{bmatrix} = \begin{bmatrix}0 & 1-0.1\varepsilon\end{bmatrix} \approx \begin{bmatrix}0 & 1\end{bmatrix}\)
- \(\underbrace{\begin{bmatrix}0 & 1 \\ 1 & 0\end{bmatrix}}_{P}\underbrace{\begin{bmatrix}1 & 0 \\ \varepsilon & 1\end{bmatrix}}_{L}\underbrace{\begin{bmatrix}1 & 0.1 \\ 0 & 1\end{bmatrix}}_{U} \approx \begin{bmatrix}\varepsilon & 1 \\ 1 & 0.1\end{bmatrix} = A\), with \(x \approx \begin{bmatrix}0.9 & 1\end{bmatrix}^{\top}\)
Pivoting: Numerical Check
eps = 2 * np.finfo(float).eps
A = np.array([[eps, 1.0], [1.0, 0.1]])
b = np.ones(2)
m = A[1, 0] / A[0, 0]
L = np.array([[1.0, 0.0], [m, 1.0]])
U = np.array([[eps, 1.0], [0.0, 0.1 - m]])
y = solve_triangular(L, b, lower=True)
x = solve_triangular(U, y)
with np.printoptions(precision=17):
    print(f"Without pivoting:\nL @ U =\n{L @ U}\nx = {x}")
P, L, U = lu(A)
y = solve_triangular(L, P.T @ b, lower=True)
x = solve_triangular(U, y)
with np.printoptions(precision=17):
    print(f"With pivoting:\nP @ L @ U =\n{P @ L @ U}\nx = {x}")
Without pivoting:
L @ U =
[[4.440892098500626e-16 1.000000000000000e+00]
[1.000000000000000e+00 0.000000000000000e+00]]
x = [1. 0.9999999999999996]
With pivoting:
P @ L @ U =
[[4.440892098500626e-16 1.000000000000000e+00]
[1.000000000000000e+00 1.000000000000000e-01]]
x = [0.9 0.9999999999999996]LU Decompositions and Systems of Equations
- General dense
solveuses LU with partial pivoting (Gaussian elimination). - For invertible \(A = P L U\), solve \(Ax=b\) using two triangular systems:
- Solve \(L y = P^{\top} b\) by forward substitution.
- Solve \(U x = y\) by backward substitution.
- Each solve costs \(O(N^2)\) once the \(O(N^3)\) factorization is available.
- To compute \(A^{-1}\), solve \(L Y = P^{\top}\), then \(U X = Y\): \(X = A^{-1}\).
Backwards Substitution Example
\[ \begin{aligned} U x &= b\\ U &\equiv \begin{bmatrix} 3 & 1 \\ 0 & 2 \\ \end{bmatrix}, \quad b = \begin{bmatrix} 7 \\ 2 \\ \end{bmatrix} \end{aligned} \]
Solving bottom row for \(x_2\)
\[ 2 x_2 = 2,\quad x_2 = 1 \]
Move up a row, solving for \(x_1\), substituting for \(x_2\)
\[ 3 x_1 + 1 x_2 = 7,\quad 3 x_1 + 1 \times 1 = 7,\quad x_1 = 2 \]
Generalizes to many rows. For \(L\) it is “forward substitution”
Use Triangular Structure if Possible
- Triangular matrices of size \(N\) can be solved with back substitution in \(O(N^2)\)
- Is \(O(N^2)\) good or bad? Beats, \(O(N^3)\) typical of general methods
Symmetric Matrix Structure
Another common matrix type is symmetric, \(A = A^{\top}\)
Permutation Matrices
- Exactly one \(1\) in each row and column; zeros elsewhere.
- \(PA\) reorders the rows of \(A\): here, rows \(1,2,3\) cycle to order \(2,3,1\), while row \(4\) stays fixed.
- \(P^{\top}P = I\), so \(P^{-1} = P^{\top}\).
\[ P = \begin{bmatrix}0 & 1 & 0 & 0 \\ 0 & 0 & 1 & 0 \\ 1 & 0 & 0 & 0 \\ 0 & 0 & 0 & 1\end{bmatrix}, \qquad P^{-1} = P^{\top} = \begin{bmatrix}0 & 0 & 1 & 0 \\ 1 & 0 & 0 & 0 \\ 0 & 1 & 0 & 0 \\ 0 & 0 & 0 & 1\end{bmatrix}. \]
Linear Transformations and Orthogonal Matrices
Matrices as Linear Transformations
- Recall: for \(x \in {\mathbb{R}}^N\) we should think of a \(f(x) = A x\) for \(A\in{\mathbb{R}}^{M \times N}\) as a linear transformation from \({\mathbb{R}}^N\) to \({\mathbb{R}}^M\)
- Definition of Linear: \(f(a x_1 + b x_2) = a f(x_1) + b f(x_2)\) for scalar \(a,b\)
- Similarly, the \(y = f(x) = A x\) then \(f^{-1}(y) = A^{-1} y\) goes from \({\mathbb{R}}^M\) to \({\mathbb{R}}^N\)
- If the matrix is square and invertible, we can go back and forth without losing information (i.e., bijective). Otherwise we may be projected onto a lower-dimensional “manifold”.
Orthogonal Matrices — Definition
Orthogonal Matrix
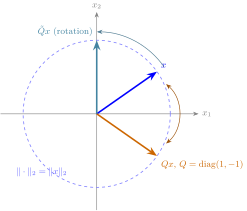
A square matrix \(Q\) is orthogonal if \(Q^{\top} Q = Q Q^{\top} = I\), equivalently \(Q^{-1} = Q^{\top}\).
- Columns are orthonormal: if \(Q = \begin{bmatrix} q_1 \; | \; \ldots \; | \; q_N \end{bmatrix}\) then \(q_i \cdot q_j = 0\) for \(i \neq j\) and \(q_i \cdot q_i = 1\)
- Geometric action: combination of rotation and/or reflection
- Inverse action: if \(y = Q x\), then \(x = Q^{\top} y\).
- Example (reflection): \(Q = \begin{bmatrix}1 & 0 \\ 0 & -1\end{bmatrix}\) flips the second component while preserving \(\|\cdot\|_2\).
Orthogonal Matrices — Preserving Norms
- Rotation and reflection preserve lengths
- For all \(x \in {\mathbb{R}}^N\), \(\|Q x\|_2 = \|x\|_2\).
- Proof: \(\|Qx\|_2^2 = (Qx) \cdot (Qx) = (Q x)^{\top} Q x = x^{\top} Q^{\top} Q x = x^{\top} x = \|x\|_2^2\).
Orthogonal Matrices — Preserving Angles
- For any \(x_1, x_2 \in {\mathbb{R}}^N\), \((Q x_1) \cdot (Q x_2) = x_1 \cdot x_2\).
- Proof: \((Q x_1) \cdot (Q x_2) = (Q x_1)^{\top} (Q x_2) = x_1^{\top} Q^{\top} Q x_2 = x_1^{\top} x_2 = x_1 \cdot x_2\).
- Orthogonal maps preserve inner products/“angles”
- e.g., rotate both the \(x_1\) and \(x_2\) exactly the same amount.
- Useful in many applications such as Principal Component Analysis (PCA) and cosine similarity (which is used in NLP embeddings).
Eigenvalues and Eigenvectors
Eigenvalues and Eigenvectors
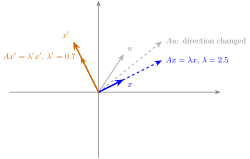
- For a square \(A\), an eigenvector \(x\) and eigenvalue \(\lambda\) satisfy
\[ A x = \lambda x \]
- \(A\in{\mathbb{R}}^{N\times N}\) has \(N\) eigenvalue/eigenvector pairs, possible multiplicity of \(\lambda\)
- Intuition: \(x\) is a direction \(A x \propto x\) and \(\lambda\) says how much it “stretches”
Properties of Eigenvalues and Eigenvectors
- For any eigenvector \(x\) and scalar \(c\) then \(c x \propto A x\) as well
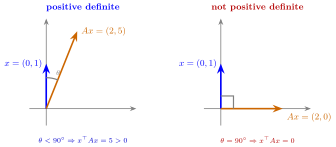
- Symmetric matrices have real eigenvalues and orthogonal eigenvectors. i.e. \(x_1 \cdot x_2 = 0\) for \(x_1 \neq x_2\) eigenvectors. Complex in general
- Singular if and only if it has an eigenvalue of zero
- Diagonal matrix has eigenvalues as its diagonal
- Triangular matrix has eigenvalues as its diagonal
Eigen Decomposition (General)
For real square matrix \(A\) we may be able to take the eigenvectors as columns of \(Q\) (eigenvectors) and a diagonal matrix \(\Lambda\) of the eigenvalues such that
\[ A = Q \, \Lambda \, Q^{-1}. \]
- \(\Lambda = \mathrm{diag}(\lambda_1,\ldots,\lambda_n)\) collects the eigenvalues (zeros allowed) into a diagonal matrix.
- The eigenvectors and eigenvalues are complex in general
These do not always exist. If so, you will hear the matrix is diagonalizable.
- Essentially, this is a question of whether the eigenvectors form an \(N\) dimensional basis and hence a \(Q\) that is invertible.
Alternatively, every real matrix admits a Singular Value Decomposition (SVD)
Eigen Decomposition (Symmetric Case)
A special case of this comes from the spectral theorem, which will sometimes be referred to as a spectral decomposition
For any real symmetric matrix \(A\) (singular or not) there exist an orthogonal \(Q\) and a real diagonal \(\Lambda\) such that
\[ A = Q \, \Lambda \, Q^{\top}. \]
- Orthogonal \(Q^{\top} Q = Q Q^{\top} = I\) (so \(Q^{-1}=Q^{\top}\)); the columns of \(Q\) form an orthonormal basis of eigenvectors.
- \(\Lambda = \mathrm{diag}(\lambda_1,\ldots,\lambda_n)\) collects the real eigenvalues (zeros allowed) into a diagonal matrix. Complex in general for non-symmetric matrices, but real for symmetric \(A\).
Geometric interpretation: apply \(Q^{\top}\) (rotation/reflection) to rotate into the basis, scale by \(\Lambda\), then apply \(Q\) to rotate/reflect back.
Spectral/Eigendecomposition of Symmetric Matrix Example
Q =
[[-0.85065081 -0.52573111]
 [ 0.52573111 -0.85065081]]
Q^T Q =
[[1.0000000e+00 1.2127222e-17]
 [1.2127222e-17 1.0000000e+00]]
Q^-1 == Q^T? True
Lambda = [1.38196601+0.j 3.61803399+0.j]
Q Lambda Q^T =
[[2. 1.]
 [1. 3.]]
Spectral/Eigendecomposition of an Asymmetric Matrix Example
A = np.array([[5, 1],
              [2, 3]])
Lambda, Q = eig(A)
print(f"eigenvectors are column-by-column in Q =\n{Q}")
print(f"Q^-1 == Q^T? {np.allclose(np.linalg.inv(Q), Q.T)}") # should be False
print(f"eigenvalues are in Lambda = {Lambda}")
print(f"Q Lambda inv(Q) =\n{Q @ np.diag(np.real(Lambda)) @ np.linalg.inv(Q)}")
eigenvectors are column-by-column in Q =
[[ 0.80689822 -0.34372377]
[ 0.59069049 0.9390708 ]]
Q^-1 == Q^T? False
eigenvalues are in Lambda = [5.73205081+0.j 2.26794919+0.j]
Q Lambda inv(Q) =
[[5. 1.]
[2. 3.]]Spectral Radius is Maximum Absolute Eigenvalue
Spectral Radius
For \(A \in {\mathbb{R}}^{N \times N}\) with eigenvalues \(\lambda_1, \ldots, \lambda_N\), the spectral radius is
\[ {\varrho\!\left( {A} \right)} = \max_{i}|\lambda_i| \]
- Iterating \(x_{t+1} = A x_t\) from a \(x_0\) applies \(A\) repeatedly, so an eigenvalue with \(|\lambda_i| > 1\) makes \(A^t x_0\) explode in that eigenvector direction
- The next lecture uses \({\varrho\!\left( {A} \right)} < 1\) as the condition for such iterations to converge
Condition Numbers
Condition Number
For non-singular \(A\), the condition number is \(\kappa(A) = ||A|| \cdot ||A^{-1}||\), the ratio of the largest to the smallest singular value of \(A\). For symmetric \(A\) this is \(\kappa(A) = \left|\frac{\lambda_{\text{max}}}{\lambda_{\text{min}}}\right|\) for \(\lambda\) the eigenvalues of \(A\).
For other matrices the eigenvalues can be far from the singular values
Sense of relative dispersion and consistent scaling
For example, using the fact that a diagonal matrix has its eigenvalues on the diagonal
\[ A = \begin{bmatrix} 1 & 0 \\ 0 & 0.001 \end{bmatrix} \]
- \(\kappa(A) = 1/0.001 = 1000\) and \({\varrho\!\left( {A} \right)} = 1\).
Or, the best we can do is \(\kappa(A) = 1\) for the identity (or any orthogonal matrix)
Interpreting Condition Numbers
- Scale free measure of numerical issues for a variety of matrix operations
- Intuition: if \(\kappa(A) = K\), then \(b \to b + \Delta b\) change in \(b\) amplifies to a \(x \to x + K \Delta b\) error when solving \(A x = b\).
- The relative error, \(||x - x_{\text{approx}}||/||x||\) is roughly \(\kappa(A) \cdot {\epsilon_{\mathrm{mach}}}\)
- if \(\kappa(A) \approx 10^{16}\) errors amplified so the scale of 100% relative error
- Poorly conditioned matrices can lead to inaccurate or wrong solutions
- Happens when the problem is at radically different scales, which can sometimes be fixed by demeaning, rescaling, etc.
- Also tends to happen when matrices are close to singular
Rules of Thumb
- Rule of thumb for standard floating points where \({\epsilon_{\mathrm{mach}}}= 10^{-16}\):
- \(\kappa(A) \approx 1\) well-conditioned
- \(\kappa(A) < 100\) fairly well-conditioned
- \(\kappa(A) < 10^{5}\) moderately ill-conditioned. Take care
- \(\kappa(A) < 10^{8}\) ill-conditioned and might introduce significant errors, especially in algorithms which repeatedly use the same calculations
- \(\kappa(A) > 10^{8}\) very ill-conditioned and likely to introduce significant errors
- Choose solution algorithms based on “numerical stability” and “conditioning” when worried
- See Matlab Docs on inv for example, where
invis a bad idea due to poor conditioning
- See Matlab Docs on inv for example, where
- Much more extreme with 32-bit floats such as when using GPUs.
Matrix Conditioning and StabilityOptional
Example with Interpolation
- Consider fitting data \(x\in{\mathbb{R}}^{N+1}\) and \(y\in{\mathbb{R}}^{N+1}\) with an \(N\)-degree polynomial
- That is, find \(c \in {\mathbb{R}}^{N+1}\) such that
\[ \begin{aligned} c_0 + c_1 x_1 + c_2 x_1^2 + \ldots + c_N x_1^N &= y_1\\ \vdots & \\ c_0 + c_1 x_N + c_2 x_N^2 + \ldots + c_N x_N^N &= y_N\\ \end{aligned} \]
- Which we can then use as \(P(x) = \sum_{n=0}^N c_n x^n\) to interpolate between the points
Writing as a Linear System
- Define a matrix of all of the powers of the \(x\) values
\[ A \equiv \begin{bmatrix} 1 & x_0 & x_0^2 & \ldots & x_0^N\\ \vdots & \vdots &\vdots & \vdots & \vdots\\ 1 & x_N & x_N^2 & \ldots & x_N^N \end{bmatrix} \]
- Then solve for \(c\) as the solution (where \(A\) is invertible if \(x_n\) are unique)
\[ A c = y \]
Solving an Example
- Solve and look at numerical error of interpolation using \(||x||_{\infty} = \max_n |x_n|\) (i.e., inf-norm)
- We already see a difference in error between using
solveandinv
N = 5
x = np.linspace(0.0, 10.0, N + 1)
y = np.exp(x)  # example function to interpolate
A = np.array([[x_i**n for n in range(N + 1)] for x_i in x])  # or np.vander
c = solve(A, y)
c_inv = inv(A) @ y
print(f"error = {norm(A @ c - y, np.inf)}, \
error using inv(A) = {norm(A @ c_inv - y, np.inf)}")
print(f"cond(A) = {cond(A)}")
error = 1.574562702444382e-11, error using inv(A) = 1.1932570487260818e-09
cond(A) = 564652.3214022254Things Getting Poorly Conditioned Quickly
N = 10
x = np.linspace(0.0, 10.0, N + 1)
y = np.exp(x)  # example function to interpolate
A = np.array([[x_i**n for n in range(N + 1)] for x_i in x])  # or np.vander
c = solve(A, y)
c_inv = inv(A) @ y # Solving with inv(A) instead of solve(A, y)
print(f"error = {norm(A @ c - y, np.inf)}, \
error using inv(A) = {norm(A @ c_inv - y, np.inf)}")
print(f"cond(A) = {cond(A)}")
error = 5.334186425898224e-10, error using inv(A) = 5.904003046452999e-06
cond(A) = 4462768125092.548Matrix Inverses Fail Completely for \(N = 20\)
- You do not need massive matrices to get into trouble
N = 20
x = np.linspace(0.0, 10.0, N + 1)
y = np.exp(x)  # example function to interpolate
A = np.array([[x_i**n for n in range(N + 1)] for x_i in x])  # or np.vander
c = solve(A, y)
c_inv = inv(A) @ y # Solving with inv(A) instead of solve(A, y)
print(f"error = {norm(A @ c - y, np.inf)}, \
error using inv(A) = {norm(A @ c_inv - y, np.inf)}")
print(f"cond(A) = {cond(A):.4g}")
error = 8.36735125631094e-10, error using inv(A) = 1057.184160412351
cond(A) = 4.126e+24Moral of this Story
- Use
solve, which is faster and can often solve ill-conditioned problems. Rarely useinv, and only when you know the problem is well-conditioned - Check conditioning of matrices when doing numerical work as an occasional diagnostic, as it is a good indicator of potential problems and collinearity
- For approximation, never use a monomial basis for polynomials
- Prefer polynomials like Chebyshev, which are as orthogonal as possible
N = 40
x = np.linspace(-1, 1, N+1)  # Or any other range of x values
A = np.array([[np.polynomial.Chebyshev.basis(n)(x_i) for n in range(N+1)] for x_i in x])
A_monomial = np.array([[x_i**n for n in range(N + 1)] for x_i in x])  # or np.vander
print(f"cond(A) = {cond(A):.4g}, cond(A_monomial) = {cond(A_monomial):.4g}")
cond(A) = 3.64e+09, cond(A_monomial) = 1.804e+18ReviewQuestions
Question Machine Epsilon
Float8 (E4M3): \({\epsilon_{\mathrm{mach}}}= 0.125\).
\[ x = 1.0, \qquad e = 0.0625. \]
What is \(x + e\), computed in float8? In float16?
| float8 | float16 | |
|---|---|---|
| A. | \(1.0\) | \(1.0625\) |
| B. | \(1.0\) | \(1.0\) |
| C. | \(1.0625\) | \(1.0625\) |
| D. | \(1.0625\) | \(1.0\) |
- float8: the spacing above \(1\) is \({\epsilon_{\mathrm{mach}}}= 0.125 > 0.0625\), so \(1.0625\) rounds to \(1.0\).
- float16: the spacing above \(1\) is \(2^{-10} \approx 0.001\), so \(1.0625\) is representable.
Question Dot Products
- \(x \cdot x = 3^2 + 4^2 = 25\).
- The dot product of a vector with itself is its squared Euclidean norm, \(\lVert x \rVert_2^2\).
Question Span
What do these two vectors span?
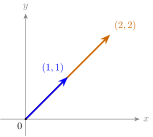
A. \(\left\{{(x,y) \in {\mathbb{R}}^2 \mid y = x}\right\}\)
B. \({\mathbb{R}}^2\)
C. \(\left\{{(x,y) \in {\mathbb{R}}^2 \mid y = x,\ x \geq 0}\right\}\)
- The vectors are collinear: \((2,2) = 2\,(1,1)\).
- Coefficients may be negative, so the span is the whole line \(y = x\), not just the ray.
Question Rank
What are the ranks of these matrices?
\[ A = \begin{bmatrix}1 & 0 & 1 \\ 0 & 1 & 1 \\ 1 & 1 & 2\end{bmatrix}, \qquad B = \begin{bmatrix}1 & 0 \\ 0 & 1 \\ 1 & 1\end{bmatrix}. \]
A. \(\operatorname{rank}(A) = 3\), \(\operatorname{rank}(B) = 2\)
B. \(\operatorname{rank}(A) = 2\), \(\operatorname{rank}(B) = 2\)
C. \(\operatorname{rank}(A) = 2\), \(\operatorname{rank}(B) = 1\)
- \(A\): the third column is the sum of the first two, so \(\operatorname{rank}(A) = 2\).
- \(B\): its two columns are independent, so \(\operatorname{rank}(B) = 2\).
Question Reusing a Factorization
An invertible \(N \times N\) matrix \(A\) has already been factored as \(A = PLU\).
What is the cost of solving \(Ax=b\) for one new \(b\)?
A. \(O(N^2)\)
B. \(O(N^3)\)
Permute the right-hand side, then solve two triangular systems:
\[ L y = P^{\top} b, \qquad U x = y. \]
Each triangular solve is \(O(N^2)\); the \(O(N^3)\) factorization is not repeated.
Question Orthogonal Transformations
Let \(Q\) be orthogonal and \(x\) be a vector.
If \(\lVert x \rVert_2 = 5\), what is \(\lVert Qx \rVert_2\)?
A. \(5\)
B. \(1\)
C. We need to know \(Q\).
Use \(Q^{\top} Q = I\):
\[ \lVert Qx \rVert_2^2 = x^{\top} Q^{\top} Q x = x^{\top} x = \lVert x \rVert_2^2. \]
Orthogonal transformations preserve Euclidean length, so \(\lVert Qx \rVert_2 = 5\).